SNWN Tech Solution delivers enterprise MLOps services to streamline machine learning lifecycle management, automate model deployment, and scale production AI infrastructure. We implement CI/CD pipelines, distributed GPU training, model monitoring, automated governance, and resilient inference architectures to optimize compute costs, minimize deployment risks, improve model reliability, and accelerate enterprise AI innovation.
Engineered for high-throughput GPU utilization, continuous automated validation, and zero training-serving skew.
Automated CI/CD pipelines cut production deployment cycles from months to hours while enforcing continuous automated validation.
Dynamic spot instance fallback, gradient accumulation, mixed-precision training, and automated hyperparameter pruning optimize hardware footprint.
Complete end-to-end lineage tracking and immutable versioning across datasets, model weights, codebases, and hyperparameter configurations.
Optimized TensorRT and Triton serving architectures paired with dynamic autoscaling deliver ultra-low latency response times under extreme peak workloads.
Siloed models stored on local machines with lost metadata, unmonitored performance, and untracked drift.
Centralized Registry: Automated artifact logging (MLflow, Weights & Biases) tracking code, weights, data distributions, and performance metrics.
On-demand GPU nodes left running idle after training jobs complete or fail unexpectedly.
Dynamic Orchestration: Kubernetes-native GPU scheduling (Kubeflow, Ray) that spins down hardware instantly post-training.
Unversioned datasets causing non-reproducible predictions, debugging friction, and audit compliance risks.
Immutable Lineage (DVC): Content-addressed storage for petabyte-scale training sets linked directly to exact model commit hashes.
Manual endpoint updates leading to operational errors, unexpected service outages, and high deployment risk.
Canary & Shadow Deployments: Progressive traffic shifting with automated real-time latency and error budget guardrails.
Models exceeding memory limits causing frequent Out-Of-Memory (OOM) crashes and degraded throughput.
Advanced Quantization: DeepSpeed, FlashAttention, and TensorRT compilation maximizing hardware compute density and throughput.
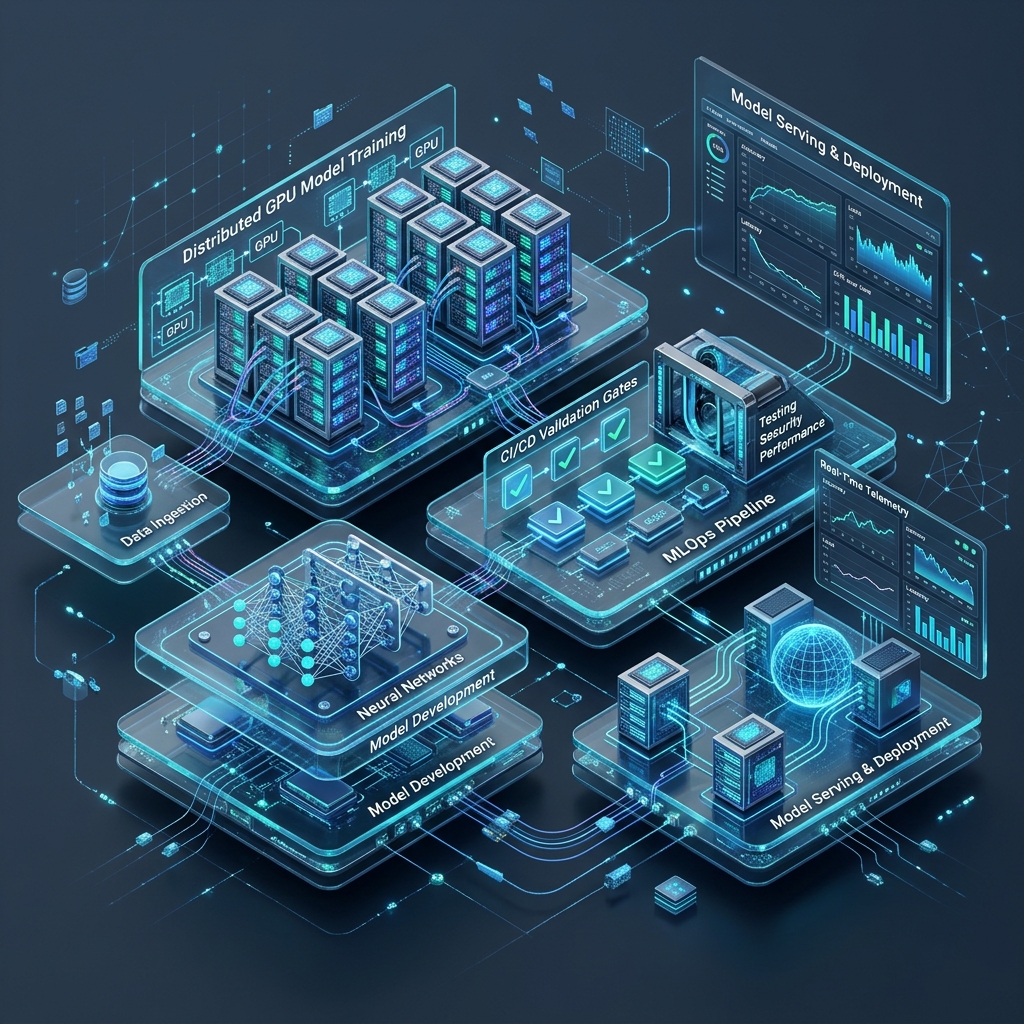
Accelerate foundation and deep learning model training across multi-node GPU clusters using PyTorch FSDP, DeepSpeed, and automated checkpoint recovery.
Build self-triggering Kubeflow and Apache Airflow MLOps pipelines that ingest streaming data, validate schemas, and enforce automated governance gates.
Deploy resilient production inference microservices powered by Triton, vLLM, and TorchServe featuring dynamic request batching, auto-scaling, and zero-downtime rollouts.
Monitor model endpoint health, latency, and accuracy in real time while proactively detecting feature drift and data distribution shifts.
Quality Management System
Information Security Management
Azure Solutions Architect
Solutions Architect & CloudOps
RHCE Linux Enterprise
Certified Systems Professional
Certified Administrator
Software Testing & Automation
Quality Management System
Information Security Management
Azure Solutions Architect
Solutions Architect & CloudOps
RHCE Linux Enterprise
Certified Systems Professional
Certified Administrator
Software Testing & Automation
Evaluate existing model development workflows, infrastructure utilization, data pipeline bottlenecks, and operational deployment risks.
Design containerized Kubernetes clusters, central model registry governance, security frameworks, and multi-cloud data storage pools.
Implement automated CI/CD workflows, validation quality gates, distributed GPU training clusters, and artifact tracking integration.
Benchmark model inference latency under peak load stress and evaluate shadow deployments against live production data streams.
Execute production rollout accompanied by live drift telemetry dashboards, automated retraining triggers, and 24/7 runbook support.
An enterprise MLOps platform bridges data science research and production software engineering to eliminate manual operational errors, ensure total governance auditability, reduce GPU resource waste by up to 65%, and accelerate model delivery timelines from months to hours.
We deploy intelligent orchestration using Ray and Kubernetes configured with spot instance fault tolerance. Automated checkpointing saves progress instantly during node preemptions and seamlessly resumes execution on new instances, substantially cutting cloud compute costs.
We standardize feature transformations and data schemas across training and inference pipelines using central feature stores (Feast) and containerized artifact registries. This guarantees that real-time inference inputs undergo the exact same mathematical preprocessing as offline training datasets.
Every candidate model must pass rigorous CI/CD benchmark suites testing evaluation metrics, inference latency bounds, fairness scores, and adversarial resilience. Only artifacts exceeding active production baseline thresholds are cleared for canary or shadow traffic routing.
Partner with SNWN Tech Solution to review your model training workflows, optimize compute efficiency, and industrialize your production AI deployment pipelines.