SNWN Tech Solution delivers enterprise Conversational AI and Natural Language Processing (NLP) solutions, combining secure large language models, production-ready RAG pipelines, and intelligent AI agents. We build context-aware conversational systems that automate workflows, retrieve enterprise data, improve customer interactions, strengthen data security, and deliver scalable, reliable business outcomes.
Engineered for real-time responsiveness, cross-lingual accuracy, and zero-trust enterprise compliance.
Autonomous conversational agents handle complex Tier-1 and Tier-2 workflows without human escalation, reducing operational overhead.
Streamed inference protocols, model quantization, and optimized local vector caching deliver real-time dialogue responsiveness.
Polyglot embedding models maintain deep semantic context and intent precision across global operations.
Complete VPC isolation, automated real-time PII redaction, and granular Role-Based Access Control (RBAC) alignment.
Brittle decision trees and exact keyword matching that fail on edge cases, domain jargon, or complex phrasing.
Semantic Vector Reasoning: Multi-head attention architectures that comprehend deep nuance, industry jargon, contextual switching, and typos.
Passive response scripts restricted to displaying static informational text and simple link redirects.
Autonomous Agentic Tool Use: Secure, multi-step API and database orchestration for end-to-end transactional execution.
Manual content imports and static database syncs leading to outdated information and high maintenance overhead.
Real-Time Hybrid RAG Indexing: Dynamic vector retrieval from enterprise knowledge bases, transactional stores, and live data streams.
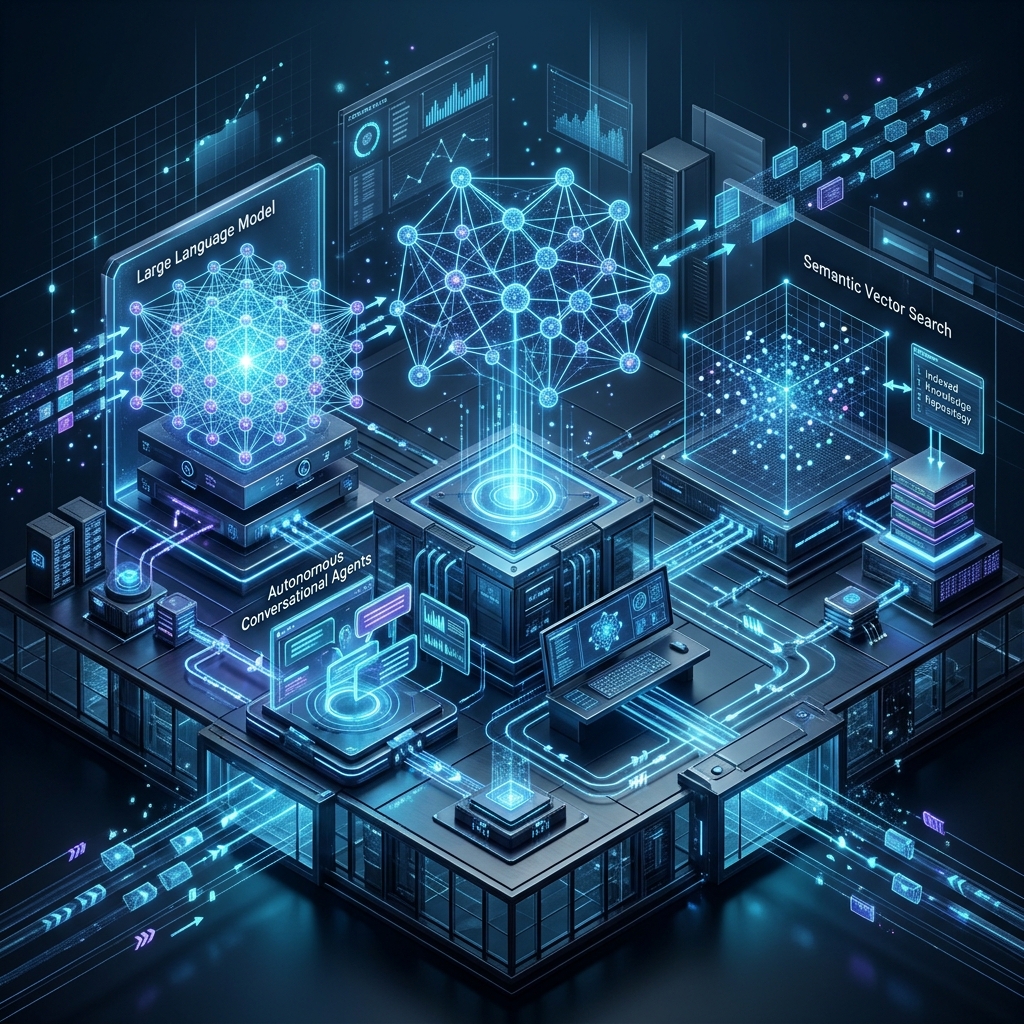
We engineer enterprise-grade Retrieval-Augmented Generation architectures that eliminate hallucinations and ground LLM outputs in verified real-time corporate data.
Configure autonomous multi-agent networks capable of deterministic tool execution, complex multi-step reasoning, transactional state persistence, and enterprise system integration.
We embed zero-trust boundaries, sovereign model isolation, and real-time data protections into every layer of conversational AI deployment.
Fine-tune open-weights LLMs using LoRA and structural quantization to deliver high-accuracy, cost-efficient models tailored to your enterprise workflows.
Build polyglot conversational AI systems featuring real-time sentiment telemetry, cross-lingual intent classification, omnichannel orchestration, and low-latency voice interfaces.
Quality Management System
Information Security Management
Azure Solutions Architect
Solutions Architect & CloudOps
RHCE Linux Enterprise
Certified Systems Professional
Certified Administrator
Software Testing & Automation
Quality Management System
Information Security Management
Azure Solutions Architect
Solutions Architect & CloudOps
RHCE Linux Enterprise
Certified Systems Professional
Certified Administrator
Software Testing & Automation
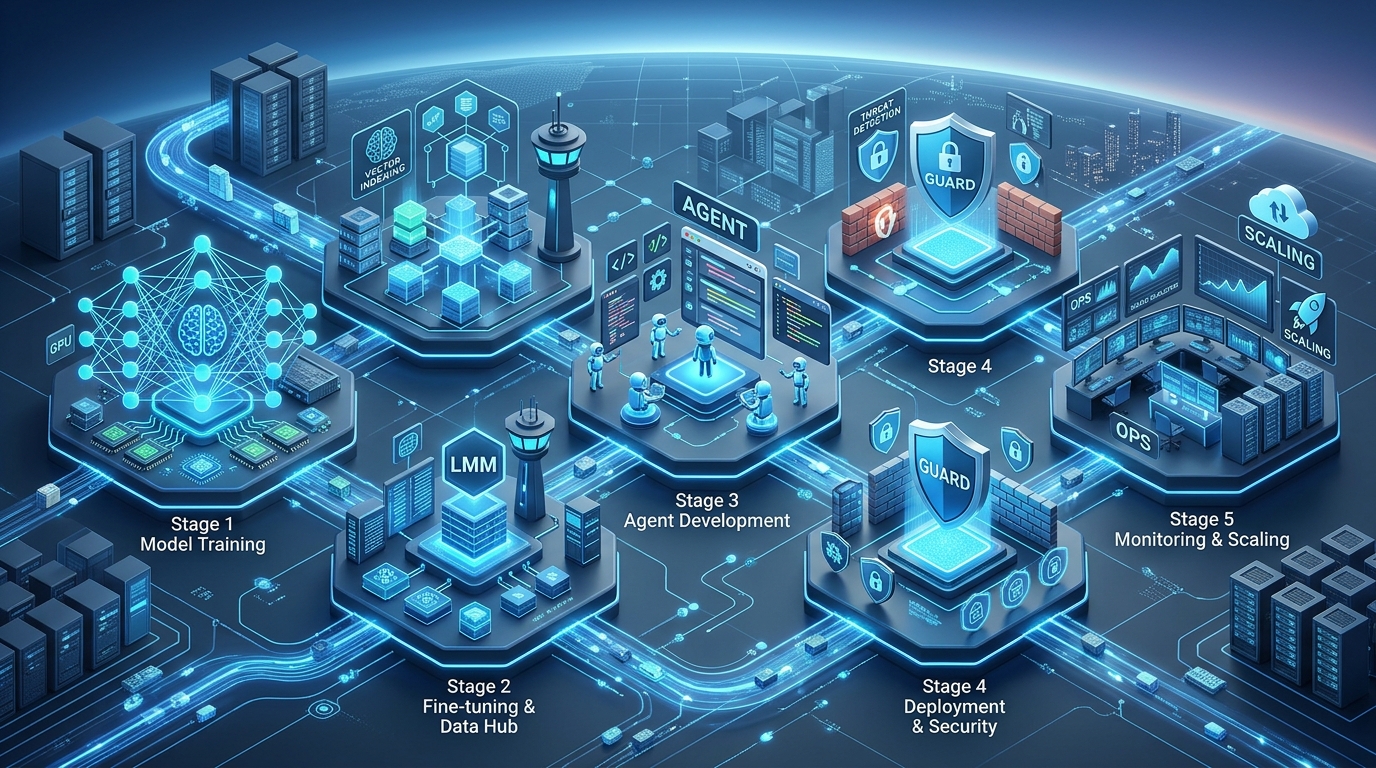
Comprehensive audit of existing workflows, data pipeline mapping, latency requirements definition, and core technical specification alignment.
Building robust ETL data pipelines, configuring vector databases (e.g., Pinecone, Qdrant, Milvus), and setting up hybrid semantic search indexing.
Developing secure REST/gRPC API wrappers, custom tool interfaces, agent decision logic, and deterministic fallback mechanics.
Rigorous adversarial testing against prompt injection, data extraction attempts, privilege escalation, and safety boundary violations.
Seamless production deployment inside your secure cloud VPC, paired with real-time observability dashboards and automated quality evaluations.
We utilize strict Retrieval-Augmented Generation (RAG) coupled with context-bounded prompt engineering and semantic cross-encoder re-ranking. If query intent lacks grounding within ingested enterprise data sources, the system executes deterministic fallback actions or seamless human agent handoffs rather than generating speculative or unverified statements.
We support fully air-gapped on-premise deployments, dedicated customer VPCs across AWS, GCP, and Azure, as well as private endpoints for zero-data-retention foundation models - ensuring end-to-end compliance with SOC 2, HIPAA, and GDPR standards.
Yes. Leveraging structured tool-calling protocols and state machine orchestration frameworks (such as LangGraph and AutoGen), agents translate natural language intents into schema-validated API and database transactions with full audit logging and state rollback mechanisms.
We optimize the entire inference pipeline through model quantization (4-bit AWQ / FP8), high-throughput engines like vLLM and TensorRT-LLM, KV-cache sharing, continuous batching, and sub-second token streaming protocols.
Consult with an experienced AI Solutions Architect to assess your technical requirements, evaluate business objectives, and review customized enterprise AI system blueprints.