SNWN Tech Solution delivers enterprise machine learning services that transform experimental models into scalable, reliable, production-ready systems. We build automated data pipelines, optimize feature engineering, monitor model drift, and implement secure ML infrastructure to improve predictive accuracy, ensure compliance, reduce operational risks, and drive measurable business performance and long-term ROI.
Delivering resilient, low-latency machine learning pipelines backed by enterprise-grade SLAs.
Auto-scaling inference endpoints delivering sub-50ms p99 latency for real-time mission-critical applications across global cloud regions.
Optimized spot instance orchestration, dynamic model quantization, automated hyperparameter pruning, and efficient distributed training architectures.
Continuous telemetry tracking data, concept, and upstream pipeline drift with automated re-training workflows to maintain predictive accuracy.
Automated MLOps CI/CD pipelines, standardized containerization, and continuous validation taking experimental models from notebooks into production in hours instead of months.
Models remain trapped in experimental notebook environments, breaking when exposed to real-world concurrent traffic and noisy data.
Production MLOps Pipelines: Containerized, version-controlled microservices deployed via automated CI/CD for continuous availability and high performance.
Accuracy decays silently post-deployment as underlying market dynamics, consumer behaviors, and environmental variables evolve.
Real-Time Drift Telemetry: Automated statistical monitors detect data and concept anomalies early, triggering automated validation and re-training loops.
Inconsistent feature engineering logic between offline training and online serving creates prediction skew and system errors.
Centralized Feature Repositories: Unified feature stores ensure absolute consistency between batch training datasets and real-time live inference engines.
Inadvertent GPU cluster sprawl, idle endpoints, and inefficient resource allocation lead to severe cloud budget overruns.
Automated Cluster Management: Dynamic compute provisioning that automatically scales and spins up resource instances strictly for execution cycles.
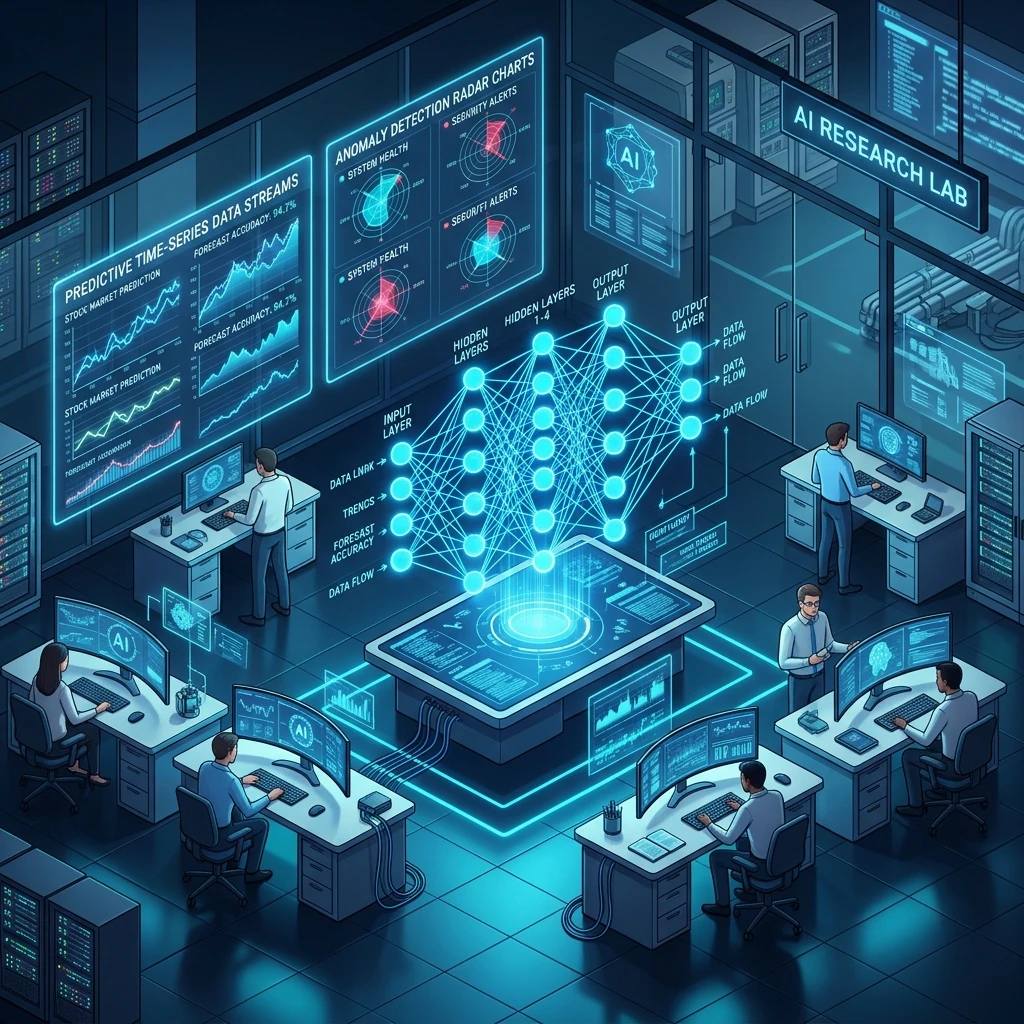
Deploy Prophet, XGBoost, and Temporal Fusion Transformer models to forecast supply chain demand, inventory levels, and financial performance accurately.
Implement ultra-low-latency streaming ML pipelines that score high-volume transactions in real time to block fraud and operational anomalies.
Extract actionable intelligence from unstructured documents, automate support ticket routing, and classify enterprise communications using fine-tuned transformer models.
Optimize deep learning models using ONNX Runtime, TensorRT, and structural quantization to deliver sub-millisecond offline inference on edge hardware.
Quality Management System
Information Security Management
Azure Solutions Architect
Solutions Architect & CloudOps
RHCE Linux Enterprise
Certified Systems Professional
Certified Administrator
Software Testing & Automation
Quality Management System
Information Security Management
Azure Solutions Architect
Solutions Architect & CloudOps
RHCE Linux Enterprise
Certified Systems Professional
Certified Administrator
Software Testing & Automation
Evaluating existing data assets, defining key performance indicators, establishing baseline operational metrics, and assessing technical readiness.
Designing reusable feature pipelines, testing candidate model architectures, validating accuracy against historical benchmarks, and quantifying business lift.
Building version-controlled execution pipelines, automated artifact registries, unit/integration test suites, and robust CI/CD deployment routines.
Executing candidate models in shadow mode alongside live traffic to validate inference stability, latency benchmarks, and edge-case handling before cutover.
Executing full production deployment paired with active drift monitoring, automated alerting systems, SLA tracking, and scheduled re-training loops.
We deploy automated MLOps pipelines integrated with continuous drift monitoring telemetry. When statistical distributions or data drift exceed predefined threshold bounds, automated re-training workflows trigger, validating the updated model against production benchmarks prior to seamless, zero-downtime deployment.
Yes. All model deployment pipelines are fully containerized using Docker and Kubernetes orchestrators. This architecture allows effortless deployment within private clouds, air-gapped on-premises infrastructure, or multi-cloud environments while adhering to strict enterprise governance standards.
Schedule a strategic technical discovery session with a Lead MLOps Engineer at SNWN Tech Solution to review your data infrastructure, identify high-impact automation opportunities, and evaluate production readiness.